Setting up event tracking without hurting privacy comes down to three decisions made before any code ships: which events you actually need, which fields those events are allowed to carry, and whether each one waits for consent. The mechanics are ordinary tag and dataLayer work. The privacy comes from what you refuse to send.
Most teams get that order wrong. They install analytics, leave a default configuration running for a quarter, then discover a form event carrying an email address and a page URL with a session token in the query string. Backfilling that means auditing every hit already stored.
This guide covers digital product analytics events — clicks, form steps, downloads, screen views. It is not about security planning for physical events, and nothing here is legal advice.
Here is the whole process in eight lines, then the detail behind each one.
- Write down the product questions you need answered, not the data you happen to have.
- Build a small event taxonomy: journeys, actions, outcomes, failure points.
- Give every event an allow-list of fields. Everything else is denied by default.
- Decide, per event, whether it needs consent before it fires.
- Pick a transport: browser tags, a first-party endpoint, or a cookieless platform.
- Implement with consent defaults set to denied, not granted.
- Test the payloads in the network tab and in the platform’s debug view.
- Review the event list on a schedule and delete anything nobody reads.
Updated for October 2026. The examples use current GA4 and Consent Mode v2 syntax rather than the deprecated Universal Analytics calls that still fill most tutorials.
Table of Contents
- What You Need
- Step-by-Step
- 1. Define what you need to measure
- 2. Choose privacy-conscious analytics tools
- 3. Set the privacy and consent rules
- 4. Implement only the events you approved
- 5. Test the setup before release
- 6. Review, limit, and improve the data
- Common Mistakes
- Frequently Asked Questions
- Do I need consent before firing analytics events?
- Can I track user behaviour without cookies?
- How do I make sure my analytics events do not contain personal data?
- How long should you keep analytics event data?
- What is the best event tracking platform for privacy?
- Is server-side event tracking worth it for a small team?
What You Need
You need five things settled before writing a single event, and three of them are documents rather than tools. Exact settings differ by analytics vendor, website builder, app framework and jurisdiction, so treat the names below as categories to check against your own stack.
- An event taxonomy document. One page listing every event name, when it fires, and which fields it may carry. If an event is not on that page, it does not go to production.
- An analytics platform with first-party options. A tag manager plus an analytics property, a cookieless first-party tool, or your own collection endpoint.
- A consent workflow. A consent management platform, a CMP plus a working tag, or a documented record of lawful basis where consent is not required.
- A retention and deletion policy. A number of days per data type, plus whoever is allowed to run a deletion.
- A way to test and review. Browser developer tools, the platform’s debug view, and a recurring calendar slot for reviewing the event list.
Decide which of those five are legal questions for someone else. A data protection officer or counsel should confirm the lawful basis and the retention period; your job is to build the mechanism they approve.
Two details worth writing down early. First, whether your analytics runs in a browser, a mobile app, or both — the consent mechanics differ sharply, because browsers have a CMP and app stores gate SDKs at build time. Second, whether any of your events touch a citizen-facing service where identifying an individual is not something you are permitted to do at all, which is a different constraint from a compliance checkbox.
Step-by-Step
The working sequence runs top to bottom: define, choose, set rules, implement, test, then review. Each step below has a check that tells you it worked, and skipping a step does not save time, it just moves the work to the quarter where you least want it.
1. Define what you need to measure
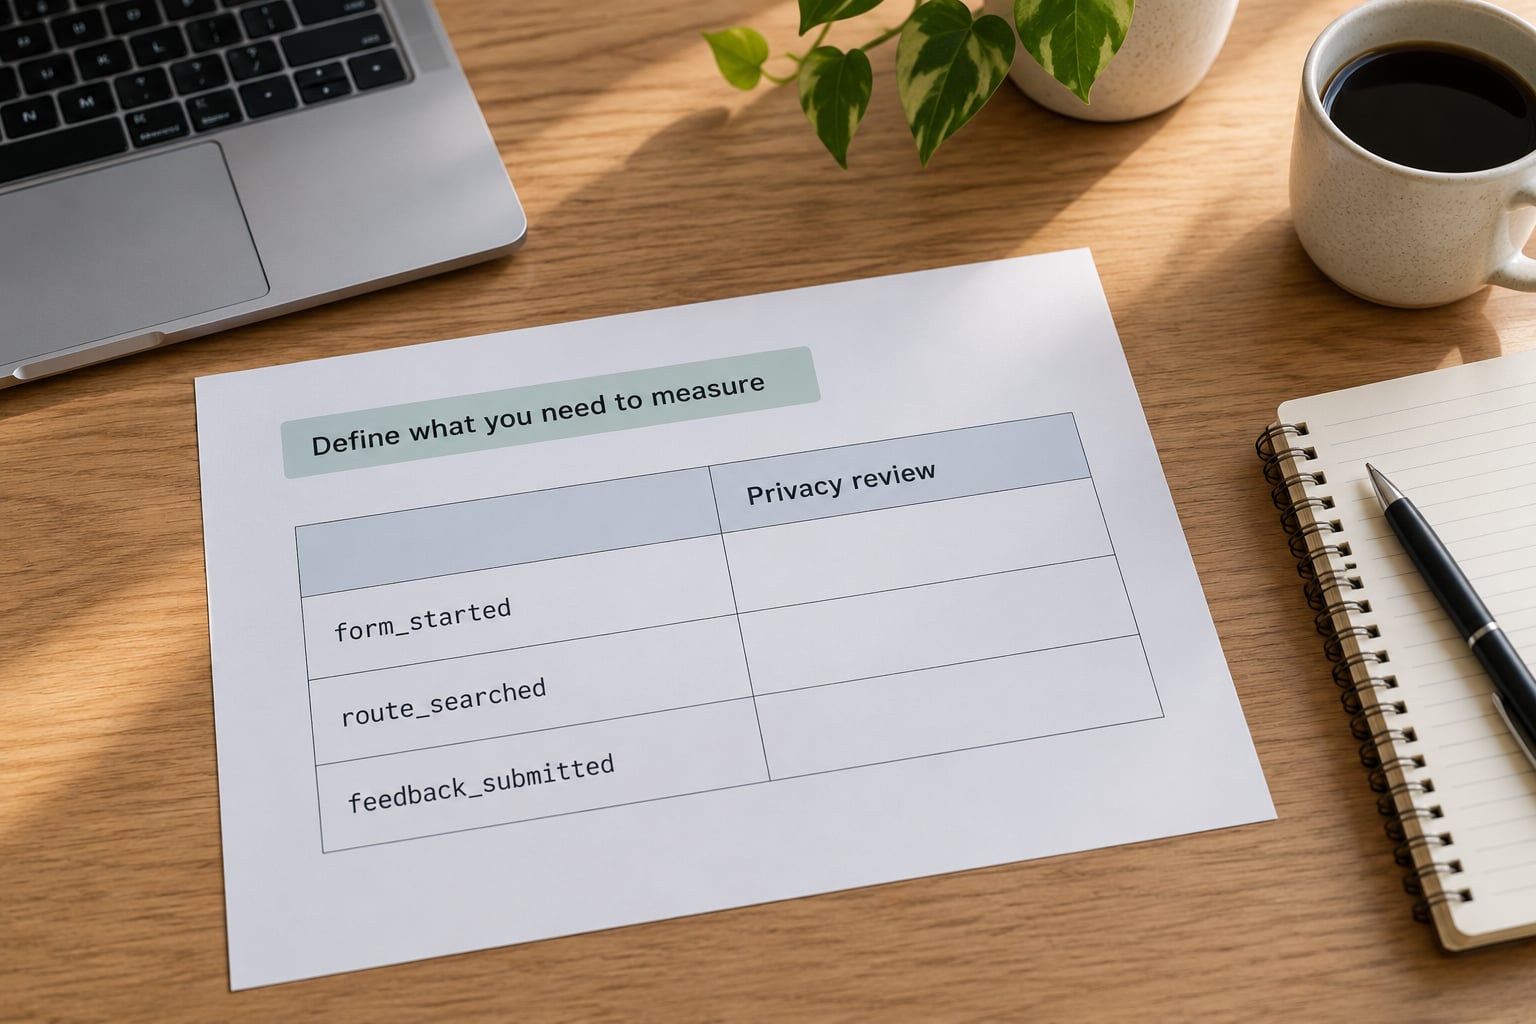
Start with product questions, not available fields. A good starting taxonomy has four groups: journeys someone travels through, actions they take inside those journeys, outcomes that count as success, and failure points where people give up. Most teams need fewer than thirty events to answer a year’s worth of questions.
Name events in the past tense, in snake_case, and describe what happened rather than where it happened on screen. feedback_submitted tells you something. clicked_button_3_on_page_7 tells you nothing and breaks the next time the layout changes.
Identify the actor without naming the person. A role or a state — anonymous, registered, trial, returning_session — answers most questions. A name, an email or a device fingerprint does not, and it converts a lightweight measurement task into a personal-data one.
It worked when: every event on your list maps to a question someone has actually asked, and you can read the whole list out loud in under two minutes.
2. Choose privacy-conscious analytics tools
Compare tools on six things: whether collection is first-party, how consent state is handled, where data is processed, who can see raw event data, whether deletion actually works, and what the entry and paid tiers look like. Vendor names change; those six questions do not.
| Approach | Privacy posture | Data quality | Setup effort |
|---|---|---|---|
| Browser tags with consent gating | Depends on the consent defaults you set; tags still fire unless blocked | Good, but ad blockers and refusals remove a visible share of hits | Low to start, grows with tag complexity |
| Server-side forwarding through your own endpoint | Stronger: identifiers can be stripped, shortened or rotated before anything leaves | Higher, because blocking a first-party endpoint is harder | Highest; needs a running service and monitoring |
| Cookieless first-party analytics | Strongest by default: no cookies, no persistent visitor identifier | Lower on returning-visitor metrics, fine on usage and funnels | Lowest; many are a snippet and a settings page |
Self-hosted or open-source tools have an underrated advantage: anyone on your team can read the tracking code and confirm what it sends. That auditability is worth a lot when the person asking the question is a compliance reviewer rather than a marketer.
For a small team, the pragmatic order is cookieless first-party first, server-side when you genuinely need conversions and have someone who will maintain the endpoint, and a full browser tag only when you need advertising or cross-site features you cannot get otherwise.
3. Set the privacy and consent rules
Document, per event, the purpose, whether consent is required, what the user can refuse, and how withdrawal works. The point is that the rule exists before the tag does, not after a complaint.
Ask two questions for every event. Does it store or transmit information that relates to an identifiable person? And does accessing it involve reading or writing to the user’s device, which is what triggers ePrivacy rules in many European jurisdictions even when the payload holds nothing personal? Either answer of yes usually means the event waits for consent.
In practice, most teams end up with three tiers: strictly necessary events that fire immediately because the service cannot work without them, consent-gated analytics events that wait for an analytics choice, and events that get cut entirely because nobody could explain what decision they support.
Set consent defaults to denied and only update them on a real user action. A default of granted means your banner is decorative, and in most consent regimes that is the specific thing that gets an organisation penalised.
gtag('consent', 'default', {
  ad_storage: 'denied',
  analytics_storage: 'denied',
  functionality_storage: 'denied',
  personalization_storage: 'denied',
  security_storage: 'granted'
});

// update only after the user chooses
gtag('consent', 'update', {
  analytics_storage: 'granted'
});
In mobile apps the same idea moves from a runtime banner to build-time configuration: you declare the data safety labels the SDK requires, and you must ship a version that respects the user’s choice rather than re-enabling collection on the next update. Ask your counsel how your specific regime treats mobile consent, because the answers differ by region.
4. Implement only the events you approved
Implementation is where a tidy taxonomy quietly becomes a privacy problem, so the rule is simple: the code that sends an event constructs the payload from a fixed list, never from whatever the page happens to have in scope.
const ALLOWED = ['service_area', 'route_mode', 'result_count_bucket', 'is_returning'];

function sendEvent(name, props = {}) {
  if (!CONSENT.analytics) return;
  const payload = {};
  for (const key of Object.keys(props)) {
    if (ALLOWED.includes(key)) payload[key] = props[key];
  }
  gtag('event', name, payload);
}

document.addEventListener('submit', (e) => {
  sendEvent('feedback_submitted', {
    service_area: 'transit',
    route_mode: 'bus',
    result_count_bucket: '10-25'
  });
});
Note what is not in that payload. No email, no typed comment, no full URL, no coordinates, no identifier from a government or national ID system, no stable cross-app advertising identifier.
Values matter as much as keys. A street-level coordinate in a transit app can identify one rider at a quiet stop. Bucketing a distance or a count into ranges keeps the analytical value and loses the person.
For server-side collection, the endpoint is where you do the stripping. Accept the request, drop anything not on the allow-list, truncate or discard the IP, generate a short-lived session identifier that expires when the session ends, and forward only what survives. A minimal version looks like this:
app.post('/collect', (req, res) => {
  if (!req.body.consent?.analytics) return res.status(204).end();
  const event = {
    name: pick(req.body.name, KNOWN_EVENTS),
    session_id: shortLivedSessionId(req),
    fields: allowList(req.body.fields)
  };
  store(event);            // raw IP never persisted
  res.status(204).end();
});
Watch your page URLs. Query strings routinely carry tokens, email addresses and search terms, and most analytics tools capture the full URL by default. Strip them at collection or configure the tool to send only the path.
On heatmaps and session recordings, the default is wrong for almost every organisation. Either turn them off, or mask every form field, every input, and anything a user types. Practitioners in tracking forums consistently call scroll-depth and heatmap data low value and high risk, and on a public-sector service that tradeoff rarely favours the heatmap.
5. Test the setup before release
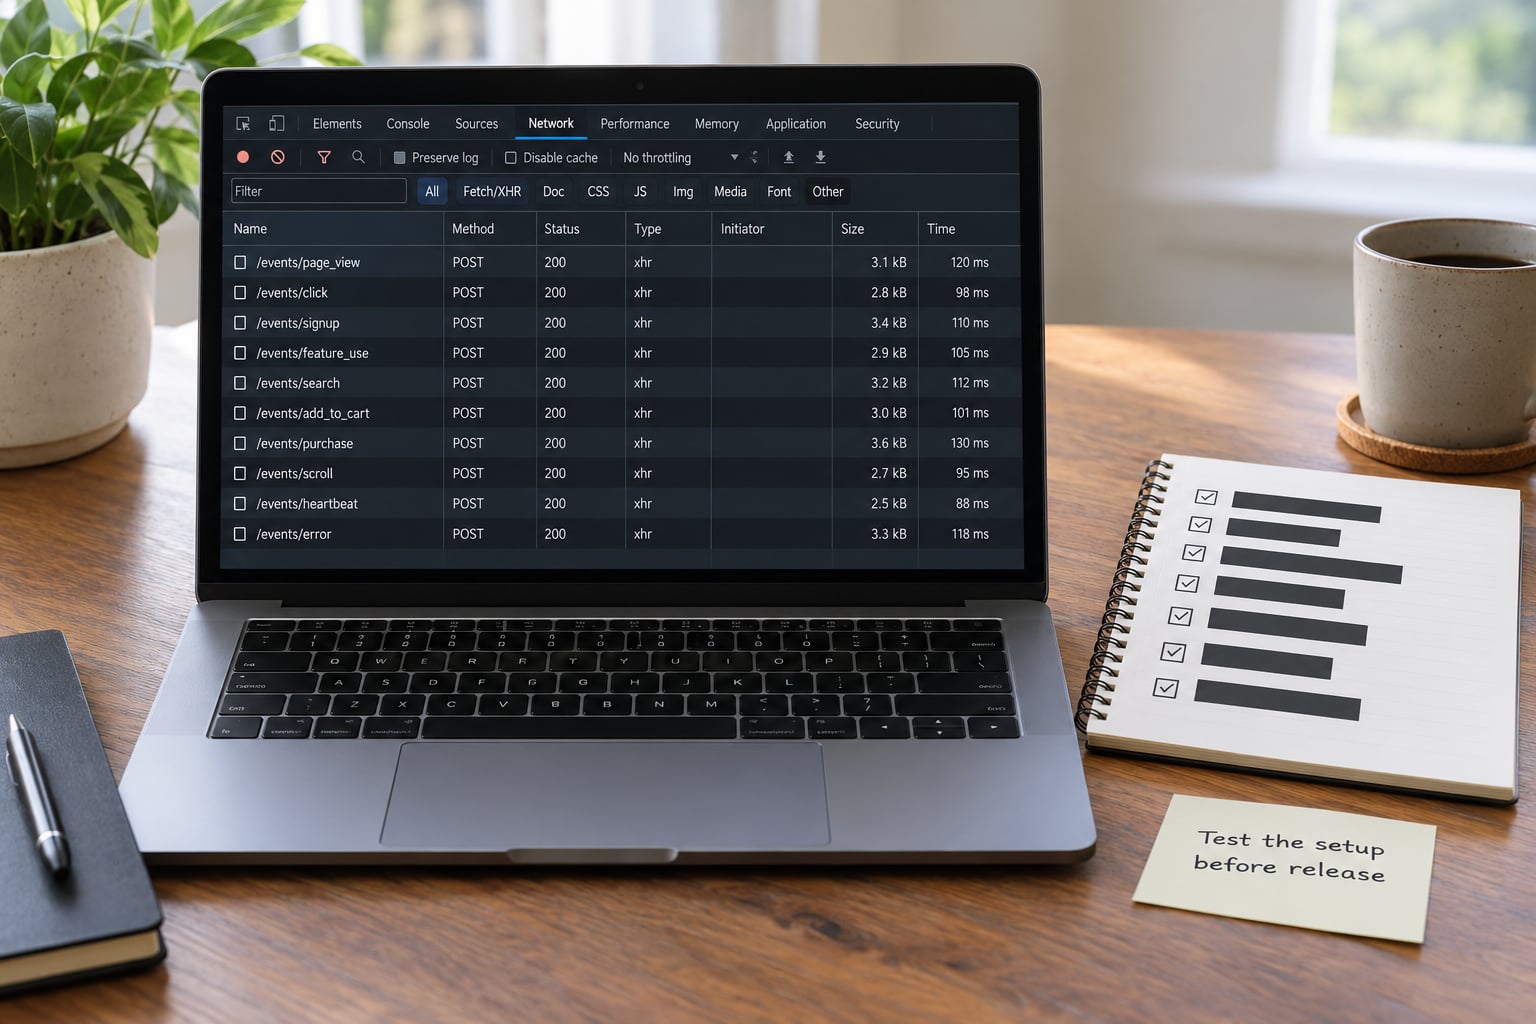
Test before release, using synthetic data, because the only reliable way to catch a leaked email address is to look at the raw request. Nobody finds these by reading the dashboard.
Run through this list with a test account and fabricated details:
- Event names. Each one fires exactly once per intended action, spelled exactly as in the taxonomy.
- Triggers. Clicking once does not produce two hits, and a page that reloads does not double-count a conversion.
- Parameters. Compare the outgoing payload against the allow-list field by field, and confirm nothing extra is riding along.
- Consent behaviour. With consent refused, no gated event should reach the network. Check the network tab, not the reporting view.
- Duplicates. Tag managers fire on both the container snippet and any manual push. Look for the same event twice.
- Redaction. Search page URLs, form values and error strings for anything a user typed.
- User agent and IP handling. Confirm the raw address is truncated, masked or discarded at the point of collection rather than trusted to be dropped downstream.
- Retention. Check that the platform’s own retention setting matches your written policy, and that a deletion request actually removes the data.
The browser network tab is the ground truth: filter to your collector, submit a form with a deliberately fake email, and read the request body. The platform’s own debug view or debug mode is the second check, and it confirms which events the tool actually accepted rather than which ones you thought you sent.
It worked when: a colleague who did not build the setup can run the list, watch every gated event stay silent with consent refused, and find nothing personal in a single payload.
6. Review, limit, and improve the data
Analytics rots quietly, so the review has to be a scheduled event with an owner rather than a good intention. A monthly thirty-minute slot catches more problems than any initial configuration.
Give the raw data a small audience. Reporting seats for product and analytics, read-only for marketing, and no raw-event export available to anyone outside that list. Most leaks are not malicious, they are a dashboard shared into a chat channel.
Set retention per data type and make it short. Raw event hits are rarely worth more than a few months, and shorter retention means a data subject erasure request is a small job instead of a project. Have the deletion run written down, with a name attached to it.
Set a threshold alert on the events that matter most, so a broken tag shows up as a drop rather than as a slow slide nobody mentions. Sampling is a legitimate tool here: if you only ever look at aggregated funnels, sampling high-volume events keeps costs and data volume down without hurting the questions you actually ask.
At each review, ask of every event the same three questions. Does anyone read it, does it change a decision, and is there a less identifying version that answers the same thing? An event that fails all three gets deleted, and a field nobody queries gets removed from the allow-list.
Worked example: a city transit app needs to know which routes lose riders at the planning step. The event is route_search_abandoned, carrying route mode and a bucketed result count, with a session identifier that expires at session end and a coarse area derived server-side from the first two digits of the origin reference rather than a device location. Nobody can reconstruct an individual journey from it, and the team can still see that night-bus searches from low-frequency areas drop off more than tram searches do.
Common Mistakes
The most common failure is treating consent as a banner problem rather than a data-collection problem. A banner you wrote in two hours does not make a non-compliant payload acceptable.
Collecting everything because the tool accepts it. A field you send is data you hold, defend on request, and eventually delete. Fix: the allow-list is enforced in code, and a new field needs a documented reason.
Firing events before consent. If the tag loads at the top of the page and pushes on scroll, refusal changes nothing about what was already sent. Fix: defaults set to denied, gating checked in code, and a consent update that re-runs the queue rather than replaying missed hits.
Using the page URL as an event name. URLs are unstable, they collide, and they carry query strings that may contain identifiers. Fix: name the action, send the path only, and strip parameters at collection.
Assuming anonymous data is harmless. A short-lived session identifier, a coarse area and a timestamp can be identifying when the population is small. Fix: minimise, aggregate, shorten retention, and get the pattern reviewed rather than the label.
Not supporting withdrawal. Users who change their mind find no way to act on it. Fix: the choice is reachable from the footer, applies immediately, and the change is written somewhere a reviewer can see it.
Exposing raw data in shared tools. A readable link in a team chat is an uncontrolled export. Fix: role-based access, no raw-event permissions outside the analytics group, and links that expire.
Confusing device data with consent. Learning that a device model, language or screen size is not personal data is not the same as being allowed to collect it. Fix: separate the question of what identifies someone from the question of what you are permitted to read from their device.
A few launch tips. Publish your event list somewhere the whole team can read, not just in an analytics folder. Make the deletion run a documented one-person job with a rehearsed script. And when someone asks whether the setup is private, give them the test procedure from step 5 rather than a policy statement — the ability to check is the trust signal.
Frequently Asked Questions
Do I need consent before firing analytics events?
Usually yes, and the test is not whether the payload holds personal data. If reading or writing data on a person’s device needs consent in your region, the event waits for it, even when the payload is a page name and a session count. Events the service cannot run without, such as a security or load-balancing check, are the narrow exception. Document the lawful basis per event and have your counsel confirm it.
Can I track user behaviour without cookies?
Yes, and on most public-facing sites that is the better default. Cookieless first-party analytics uses short-lived or no identifiers and can measure page views, journeys, funnels and errors without a persistent visitor profile. You lose reliable returning-visitor counts and any cross-site attribution. Pair it with a consent banner anyway if your regime requires one for analytics, since the absence of cookies does not automatically remove the consent question.
How do I make sure my analytics events do not contain personal data?
Test the raw request, not the dashboard. Submit a form on a test account with a deliberately fake email, open the browser network tab, filter to your collector endpoint and read the payload. Compare it field by field against your allow-list, then repeat with consent refused to confirm gated events send nothing. Add the platform’s debug view as a second check, since it shows which events were accepted rather than which ones you think you sent.
How long should you keep analytics event data?
Short enough that an erasure request is a small job. Most teams keep raw event hits for a few months, aggregate reports for longer, and keep anything tied to an account only as long as a stated purpose needs it. Write the schedule down, configure the platform’s retention setting to match, and rehearse the deletion once before you need it. A retention policy nobody has ever executed is a policy, not a control.
What is the best event tracking platform for privacy?
There is no single winner, because the answer depends on your consent posture and who maintains it. Judge tools on first-party collection, consent handling, data residency, access permissions, working deletion, and whether the tracking code can be audited. Cookieless first-party tools suit small teams best, full browser tags with Consent Mode v2 suit teams that need advertising features, and server-side forwarding suits teams with someone to run the endpoint.
Is server-side event tracking worth it for a small team?
Only if you have a specific problem it solves. It reduces blocked hits, lets you strip identifiers before anything leaves, and centralises filtering, but it adds a running service, monitoring and failure modes. Forum discussion is consistent on this point: server-side tagging is recommended constantly and is over-engineering for many small teams. Start with a cookieless first-party setup and revisit when you genuinely cannot answer a question without it.
Start tomorrow by writing the event list, not by opening the tag manager. If a product question has no event on that page yet, add one with a two-line allow-list; if an event on the page has no question behind it, delete it. Everything else in this guide — consent gating, transport, QA, retention — attaches cleanly to a short list that a team agreed on before any data was collected.